연구 게시물
45개의 게시물
HW하드웨어
5개의 게시물Assembly
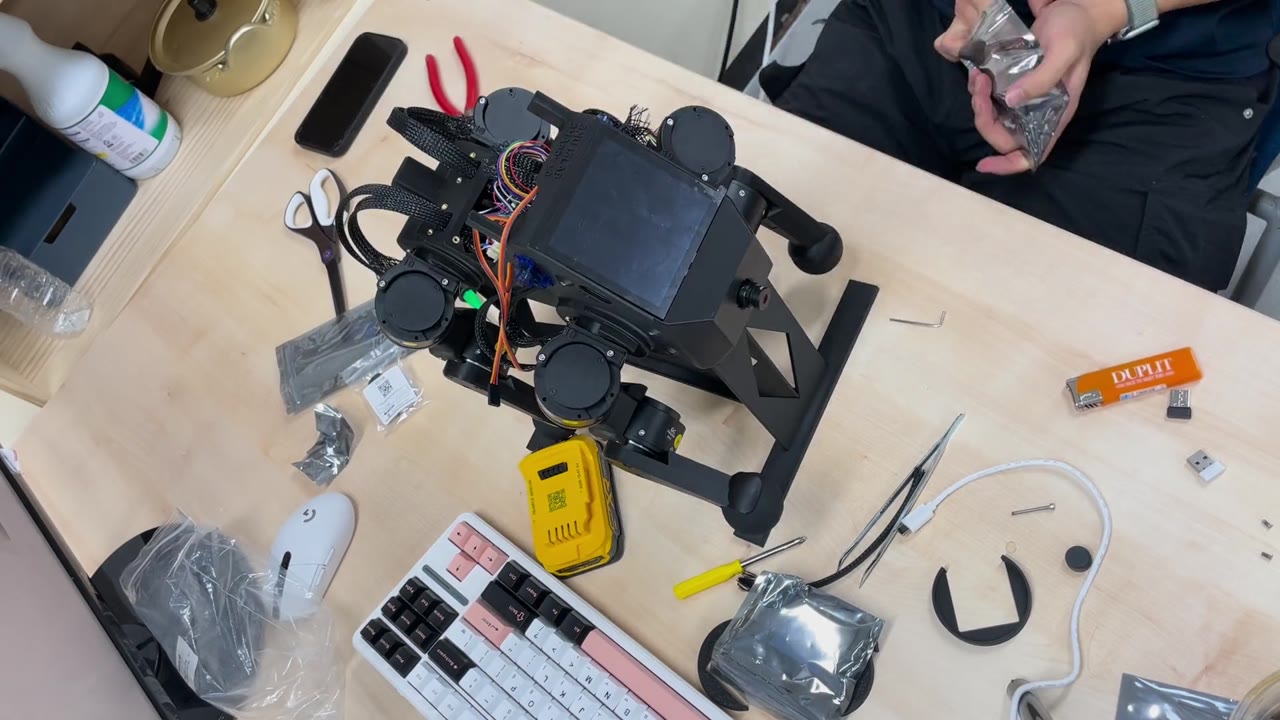
The robot being assembled on the work table, recorded from above. The timelapse runs 170 to 600 times faster than real time, fastest through the 70 minutes of cutting…
 영상
Stair course for printing: design
The simulator's test course as a printable part. One piece holds three steps, and four identical pieces make the course of three steps up and three down.
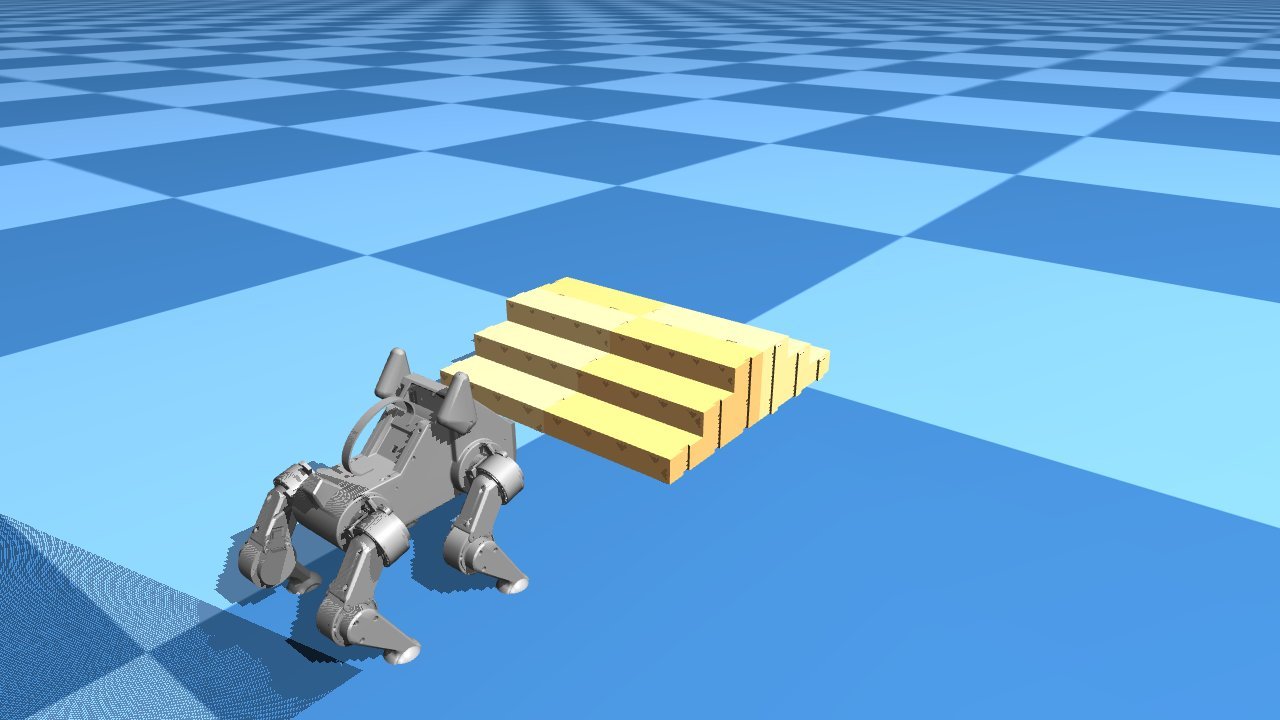 사진 / 그래프
3D printing finished
The remaining upper-leg motor brackets and front cable clamp are printed. The ears and the TPU strap are left out, so printing is done.
3D printing
Body, legs, brackets and covers printed on a Bambu Lab printer.
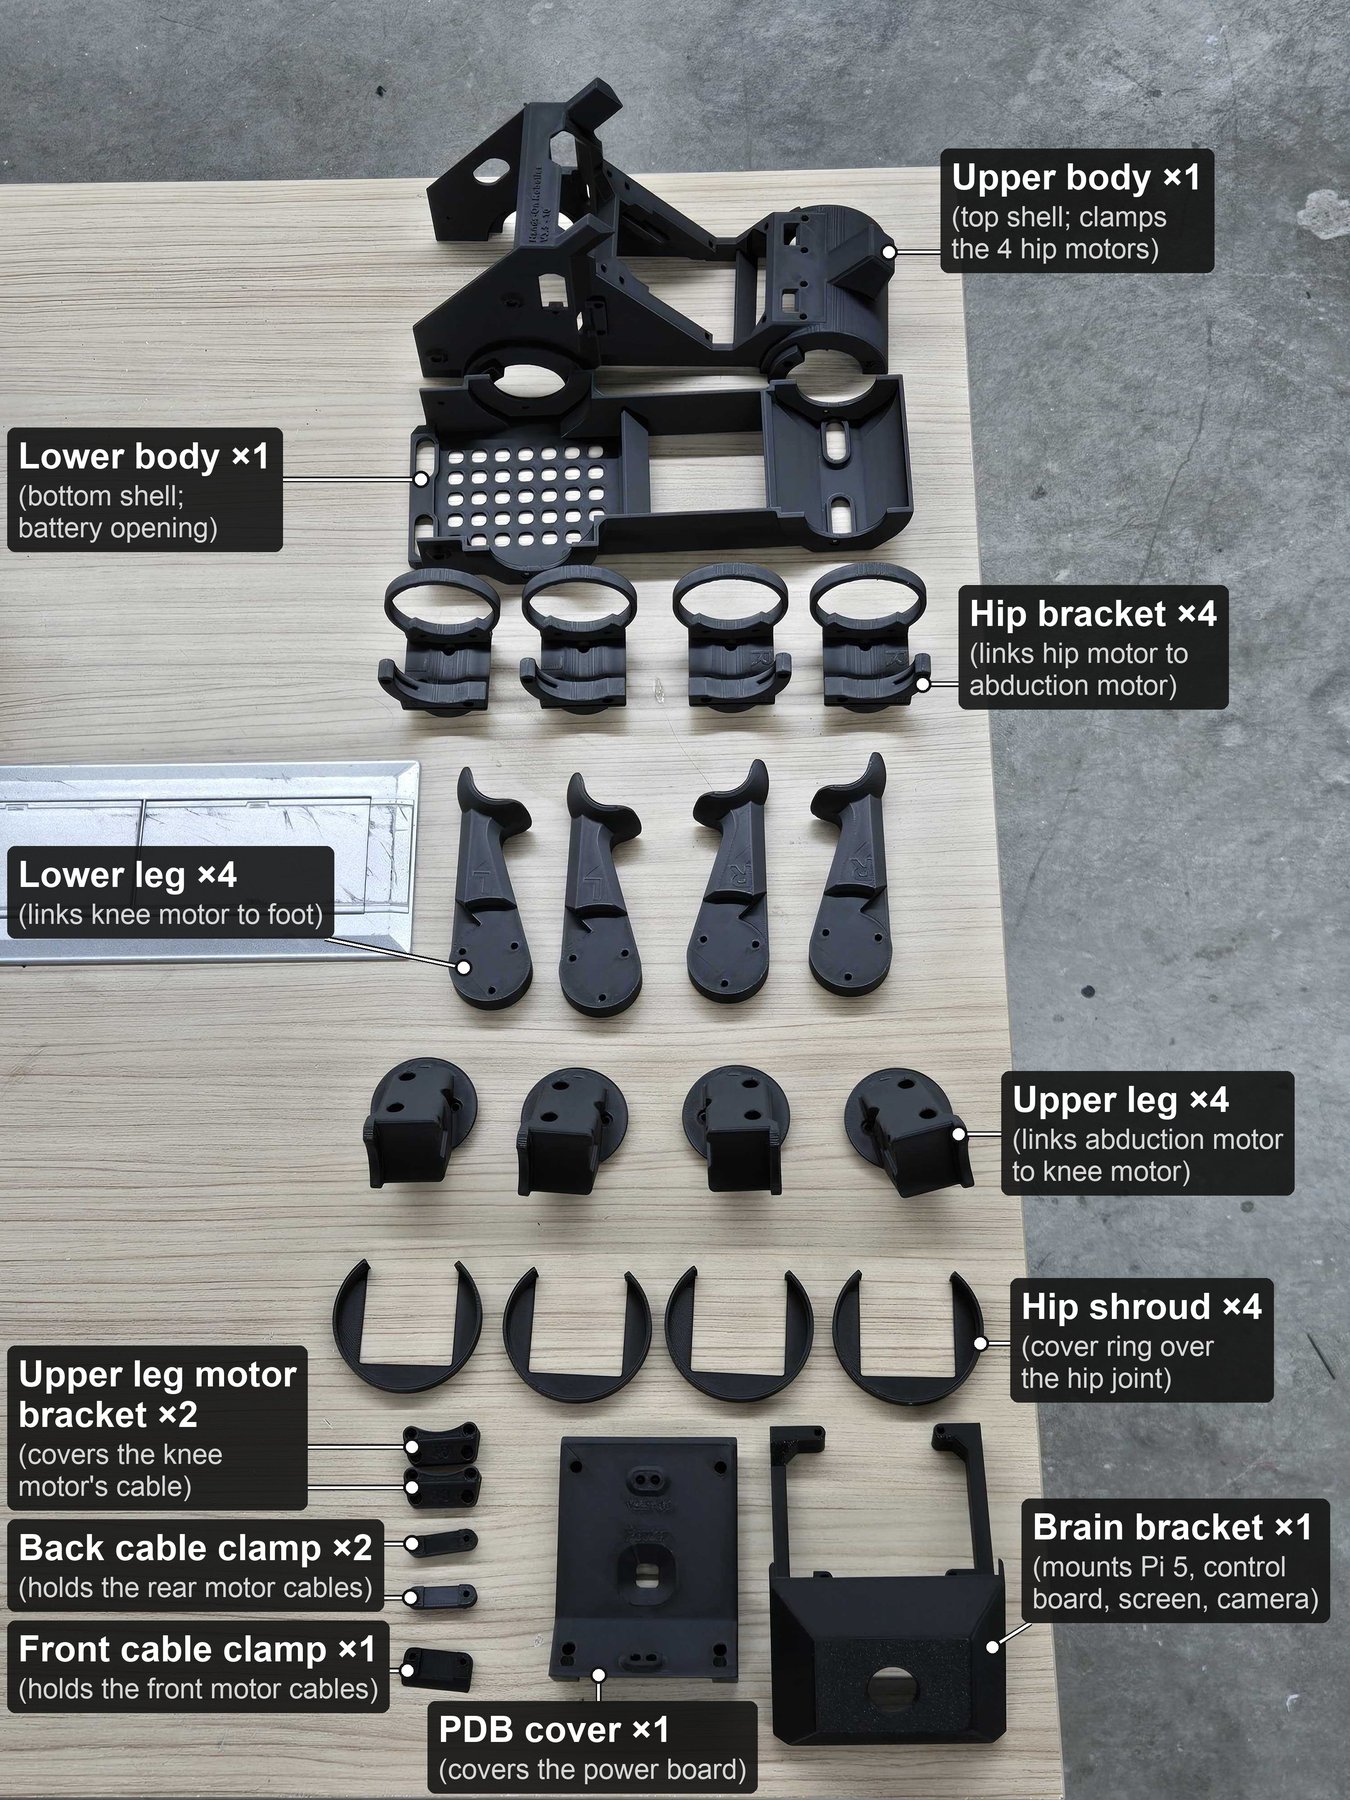 사진 / 그래프
Base design: Pupper v3
The open-source quadruped from Stanford Student Robotics, chosen as the base of the prototype.
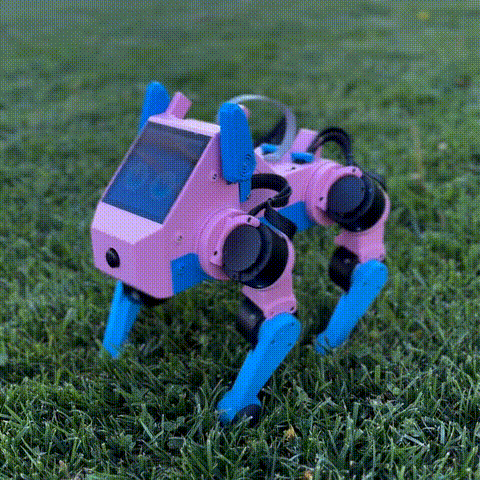 사진 / 그래프
SW소프트웨어
40개의 게시물큰 모델·긴 학습, RL은 안 늘었다
같은 과제에서 모델만 키우거나 오래 돌려도 RL은 늘지 않았고, 늘어난 사례는 목표도 넓어진 경우였습니다.
Choosing the gait: a walk trained from scratch
Gait commands had only ever produced the trot. Two policies were therefore trained from random weights, each with one gait commanded from the first step. One was…
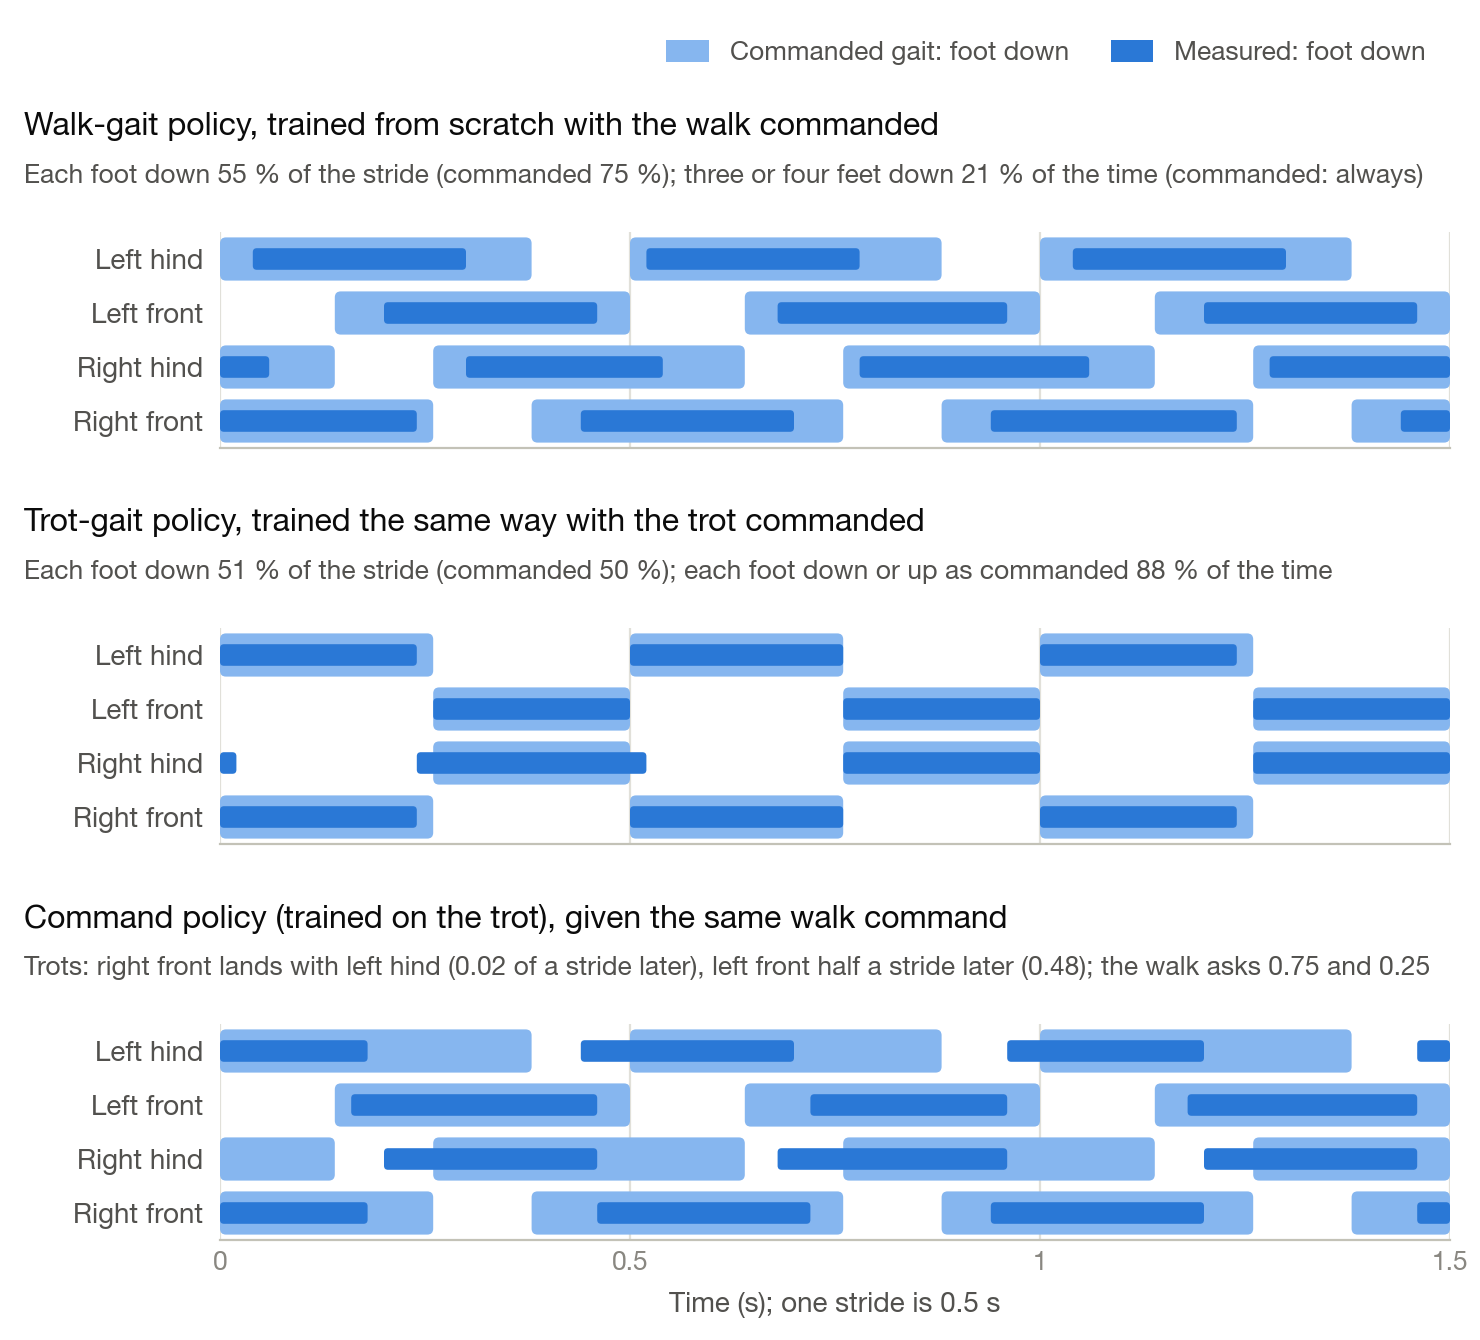 사진 / 그래프
Design note: the autonomous-intelligence architecture and Shappy
The goal is a robot with a persistent self that walks, talks and carries out varied tasks. LeCun's 2022 architecture splits that into a configurator, perception,…
 리서치 노트
V1.0 데모 계획: 음성 명령 4개
앉아·일어서·따라와·엎드려 네 명령으로 데모를 하는 계획이며, 아직 만든 것은 없습니다.
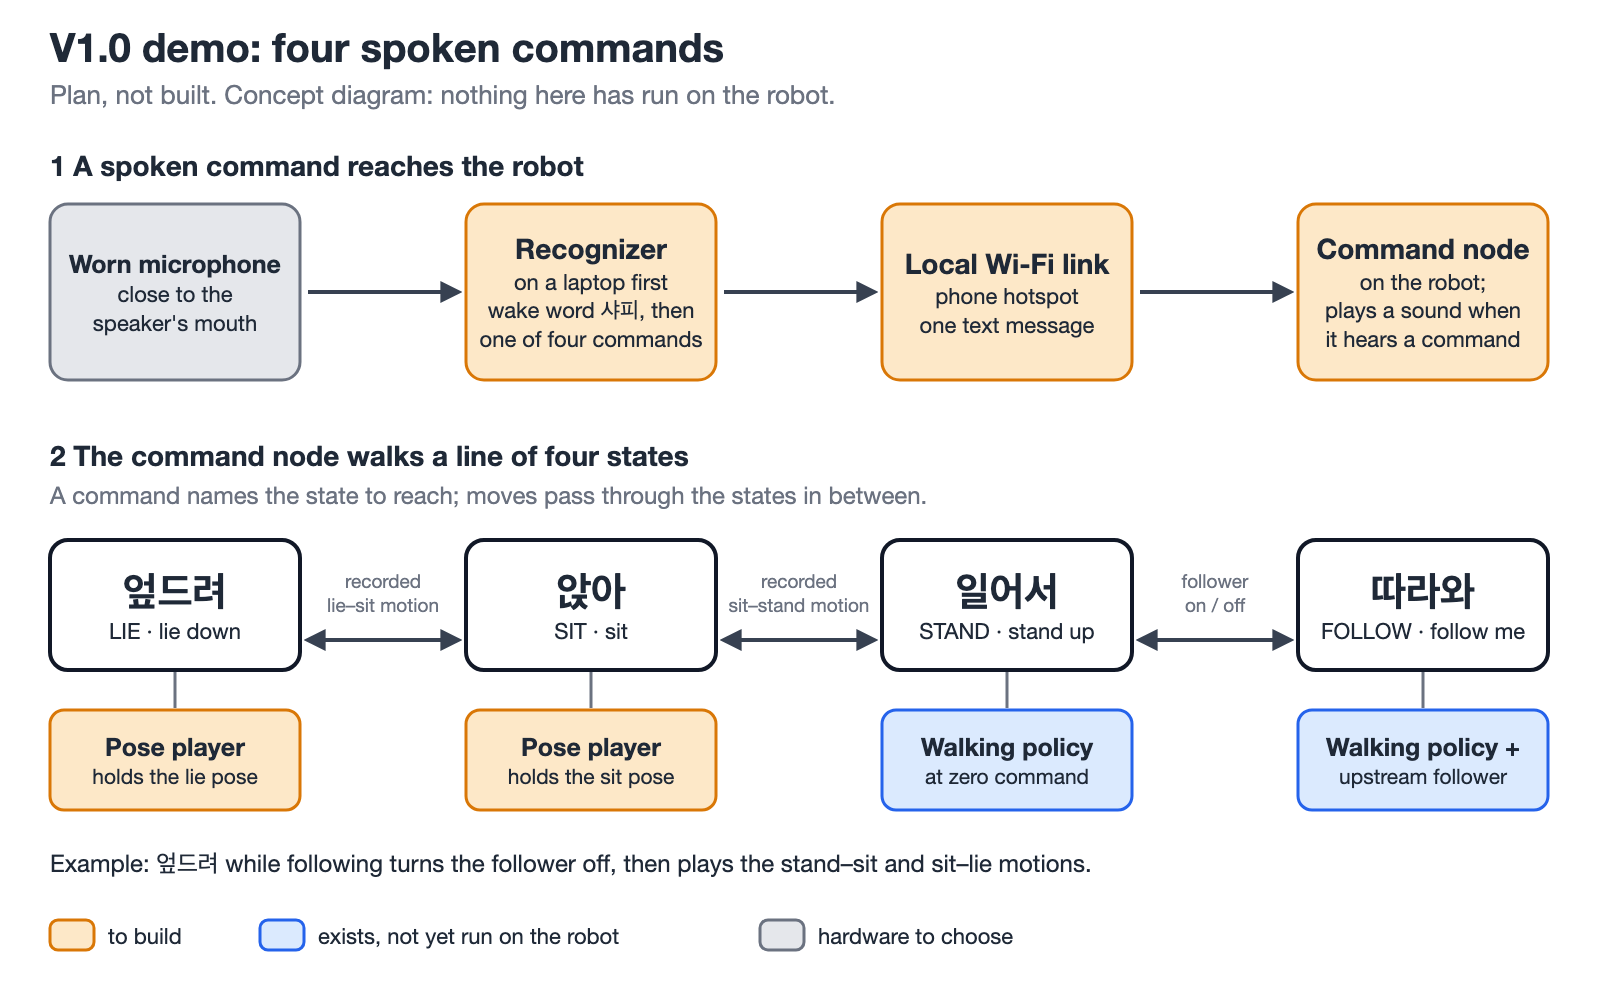 사진 / 그래프
느리게 가도 트로트인 이유
험지에는 기존 트로트를 유지하고, 네 박자 걷기를 위한 접지 비율 입력부터 추가합니다.
 리서치 노트
직진 보정: 회전은 줄고 옆밀림은 남음
방향 보정으로 회전은 잡았지만, 옆으로 밀리는 문제는 남았습니다.
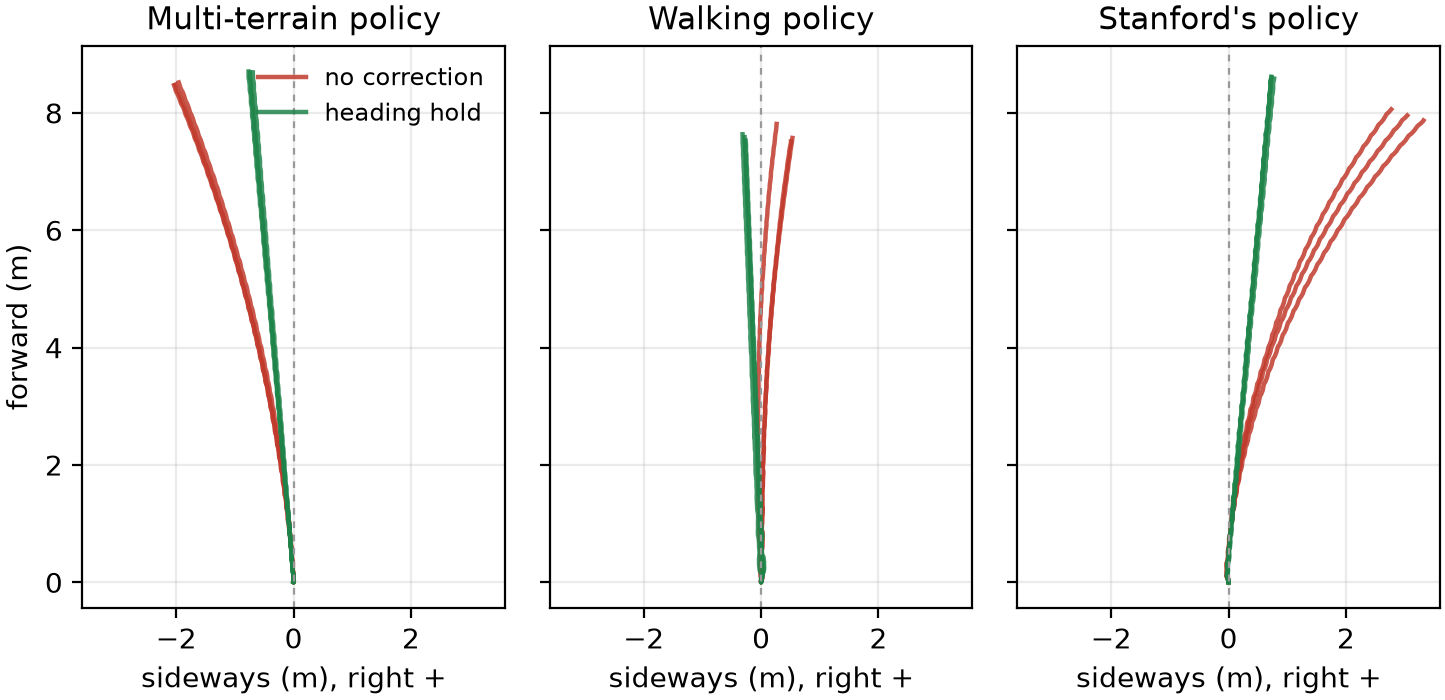 사진 / 그래프
통합 정책: 기존 조합을 아직 대체하지 못함
통합 정책으로 교체하기보다 기존 세 제어기 조합을 유지합니다.
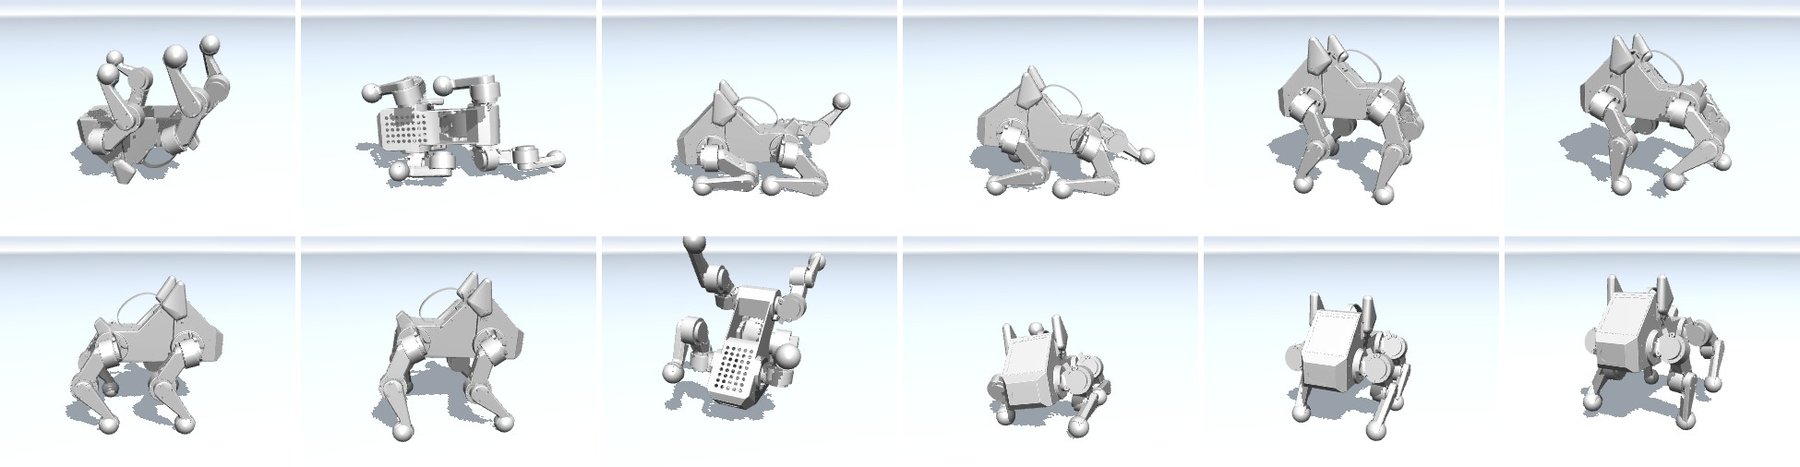 사진 / 그래프
낙상 복구: 뒤집기와 일어서기를 분담
학습 정책이 뒤집고 기존 제어기가 일으키는 조합을 시뮬레이션에서 확인했습니다.
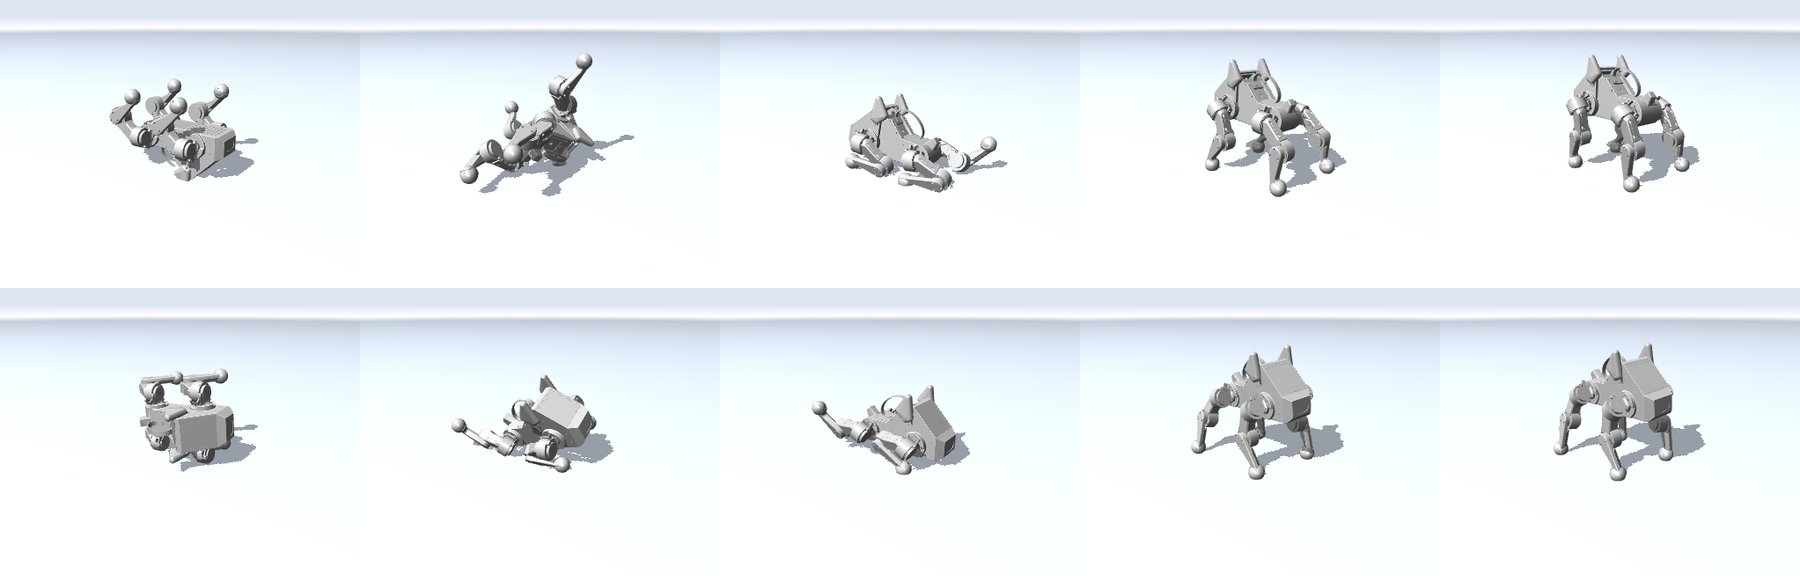 사진 / 그래프
Grass terrain
Grass joins the simulator's terrains. The pictures show it rendered as blades 3–9 cm tall; in training it slows the lower legs below the grass height, over mildly…
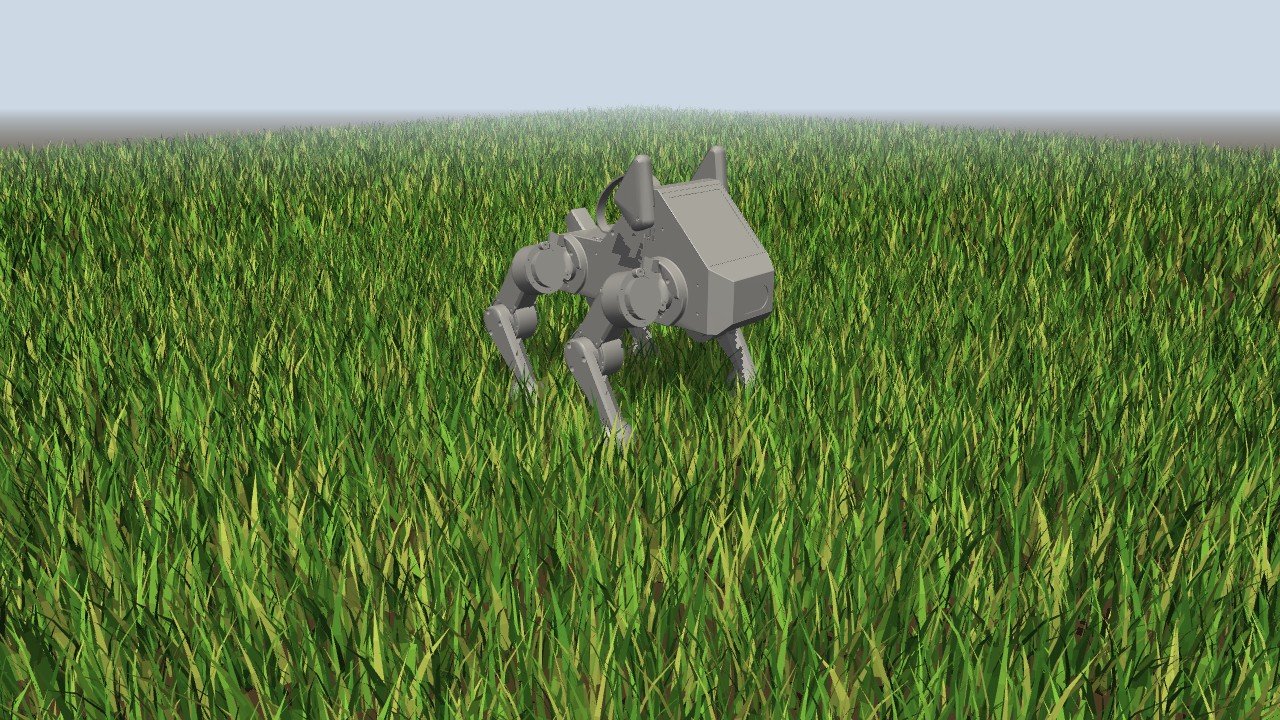 사진 / 그래프
Behaviour commands: vertical stair edges
The training simulator builds stairs and curbs on a 2 cm grid, so their edges are short ramps, while the printed course has vertical edges. The commands were…
Behaviour commands: in the robot's control software
The 1 B-step behaviour policy ran every command as trained in the robot's own control software, in simulation with the motor's joint-side constants. It was driven at…
Behaviour commands: 1 B steps with the robot's joint limits
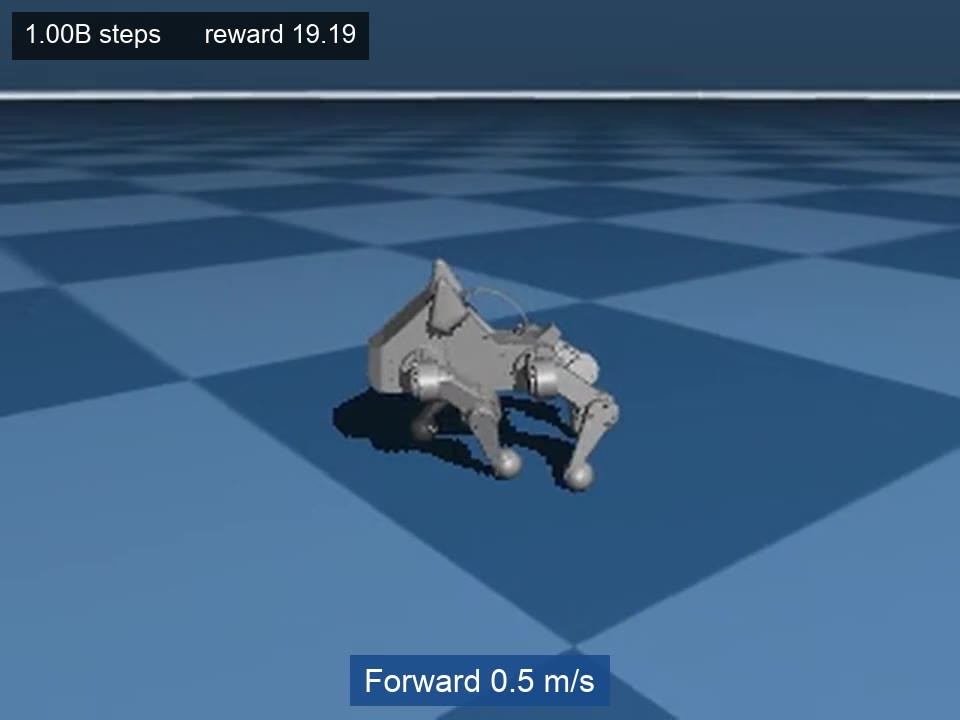
The behaviour policy trained for 1 B steps with a stronger height reward and the robot's joint limits follows every command on flat ground, the 13 cm crouch included.…
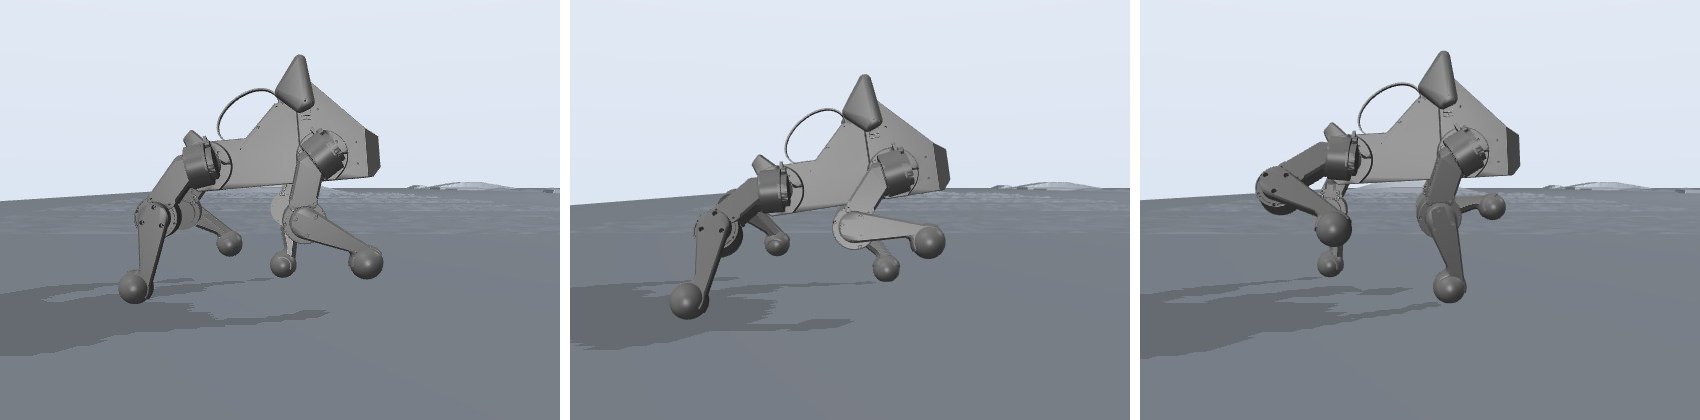 사진 / 그래프
Behaviour commands: body height on terrain
A stronger height reward makes the body-height command work, and a body held lower crosses less terrain. Most of those failures were a front leg's sideways joint at…
Residual policy in the robot's control software
The robot's controller now runs the residual policy, both networks and the behaviour inputs as trained. In the ROS 2 simulation the default walk climbs the 3 cm…
Behaviour commands: a residual policy for the commands
In one shared network, holding the default walk suppressed some of the commands. A residual policy, the multi-terrain policy frozen plus a second network that acts…
Behaviour commands: holding the default walk
Three ways to stop the falls during behaviour training changed nothing that matters. Holding the default walk to the multi-terrain policy brought its terrain skill…
Behaviour commands: where commanded behaviours are practised
Two probes changed how much of training the default walk gets and where commanded behaviours are practised. Neither brings back the 4 cm stairs; keeping commanded…
Behaviour commands: the step reward clipped at zero
Read every 5 M steps, the training logs of all behaviour runs show robots falling on flat ground far more often than the multi-terrain run. Most commanded-behaviour…
반동보다 속도·전력 한계부터
우리 모델에서는 토크보다 관절 속도·제어 방식·형상이 점프와 복원을 더 제한했습니다.
 리서치 노트
센서보다 지형 정보의 효과부터
센서를 달기 전에, 높이 정보를 본 정책이 계단 통과에 도움이 되는지 비교해야 합니다.
 리서치 노트
공중 뒤집기보다 안전한 착지부터
Pupper의 우선 과제는 공중 뒤집기보다 기울기 보정과 안전한 착지입니다.
 리서치 노트
Behaviour commands: in the ROS 2 simulator, and standing still
Behaviour policies now run in the robot's own control software in simulation, and a retrained policy stands still when no speed is commanded.
Behaviour commands: terrain-relative tilt and command limits
Two more probes on the terrain loss of the default walk, each changing one thing. Neither brings back the 4 cm stairs.
Analysis: walking speed on flat ground
The flat policy, the stair policy and the three multi-terrain policies walked the same 50 flat-ground trials at 0.3, 0.5 and 0.75 m/s, to see what training on terrain…
Behaviour commands: where the terrain loss comes from
The default walk of the behaviour runs loses the harder terrain. A control and a measurement trace about half of the loss to the behaviour reward terms charging the…
Behaviour commands: the swing-height command works
The swing-height command is followed once its reward term is scaled to Pupper's step height and the policy is trained with trot commands only. The same policy then…
Behaviour commands: reward terms and two probes
Why the first run ignored the gait and swing-height commands was read from its reward terms, and two runs of 200 M steps each changed one reward weight. Neither…
Analysis: what stair training changed
The flat policy, the stair policy and the multi-terrain policy were compared step by step in recorded walks, on flat ground and on the stair lanes, to see where the…
Behaviour commands: first run
One policy is to take commands for gait, step frequency, body height, posture and swing height besides velocity, on the multi-terrain field. The first run stopped at…
한 정책의 지형 학습은 난도 조절부터
지형을 섞어 학습하되, Pupper 크기에 맞춰 난도를 조절해야 합니다.
 리서치 노트
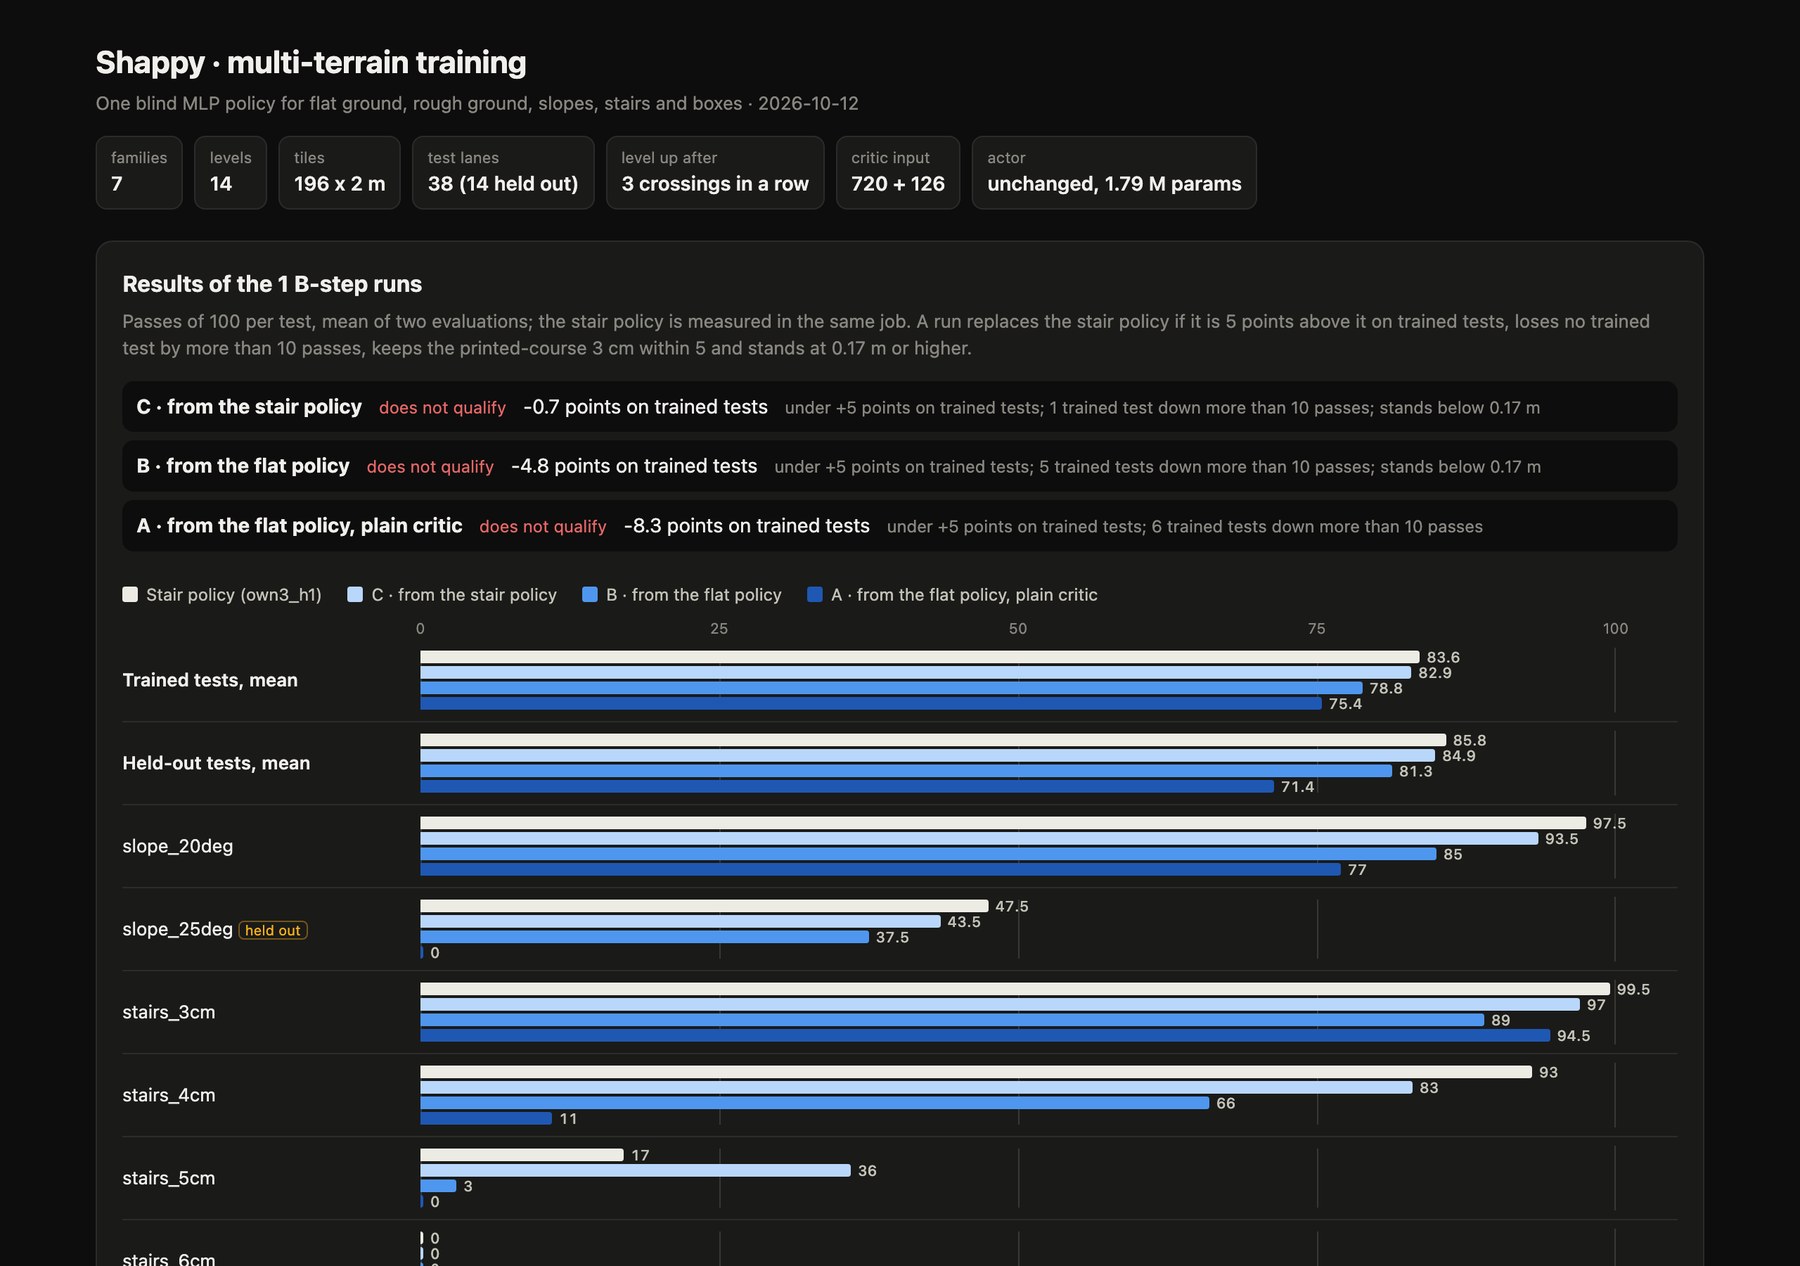
다지형 학습: 기존 계단 정책 유지
새 다지형 정책이 교체 기준을 넘지 못해 기존 계단 정책을 유지합니다.
 리서치 노트
공통 평가장: 계단 정책이 초기 기준 1위
공통 평가장을 만들었고, 당시 기준 성능은 기존 계단 정책이 가장 높았습니다.
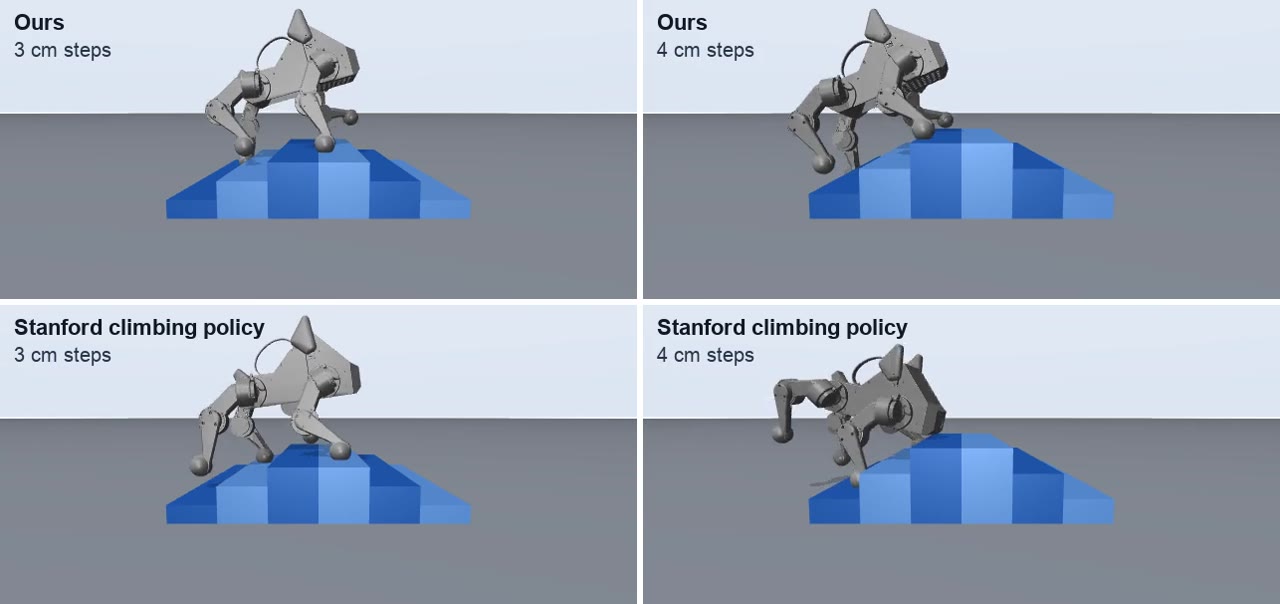
리서치 노트Stair policy: 3 cm and 4 cm steps
Our own policy crosses the stair course in simulation, three steps up and three down on 80 mm treads. It was trained from our flat policy, and Stanford's policies…
 영상
Stairs in the ROS 2 simulator
The simulation of the robot's ROS 2 stack now has the stair course, and the driving page switches between policies while the simulation runs.
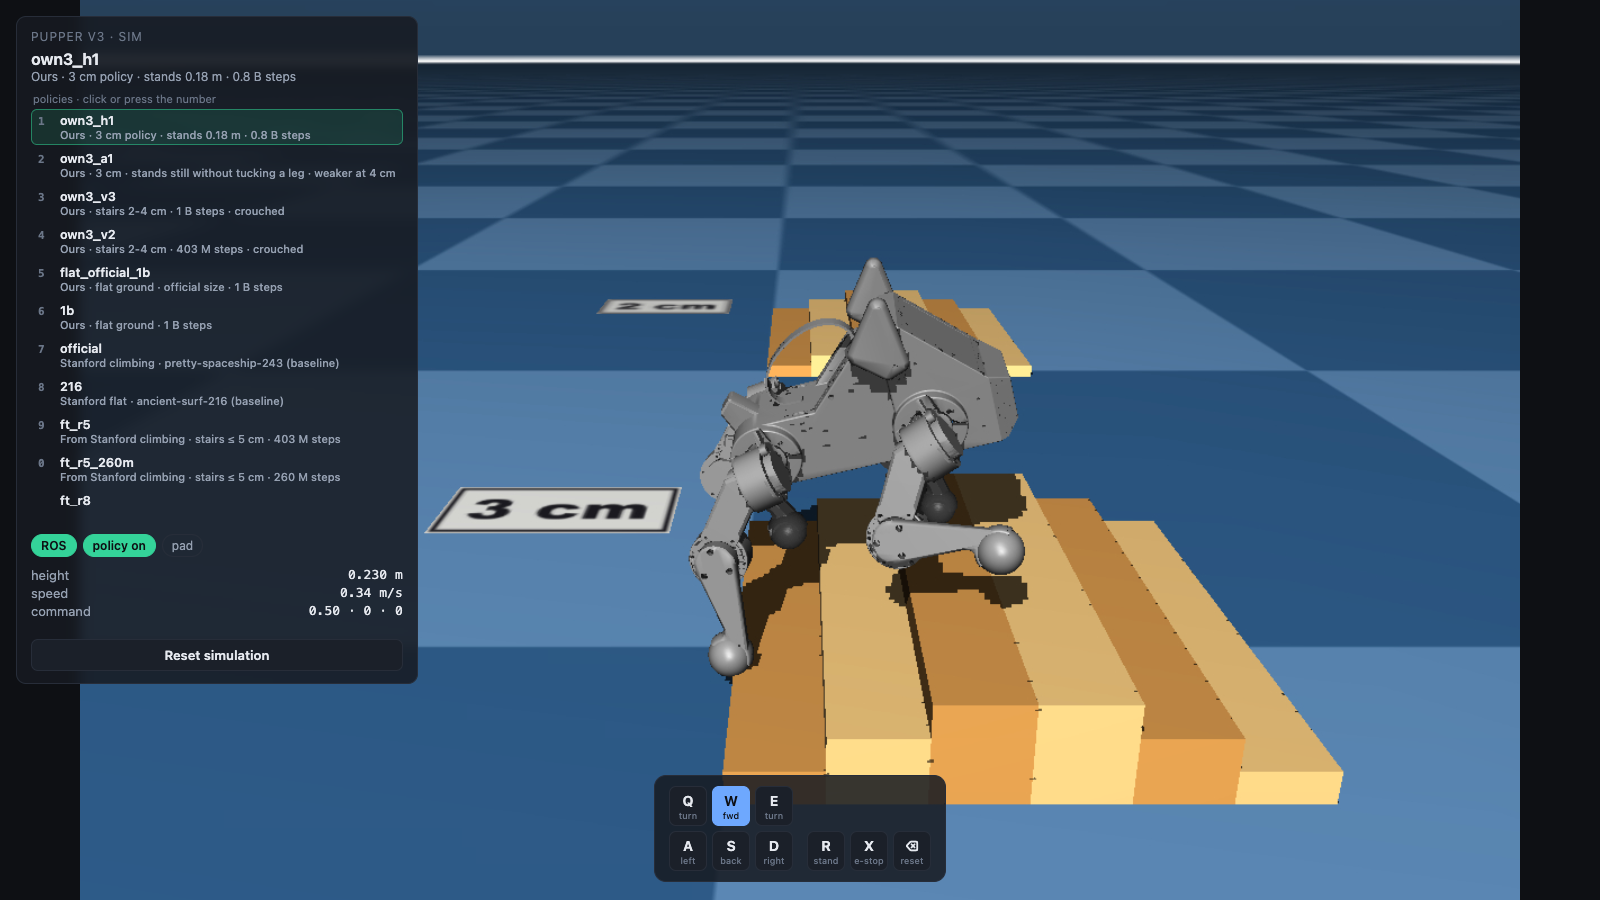 사진 / 그래프
Training on a lab PC with MuJoCo Warp
Training moved to a lab PC with an RTX 5070 Ti, and its physics from the JAX backend of MuJoCo MJX to the Warp backend. Rewards, randomization and the PPO setup are…
Experiment: one policy per direction
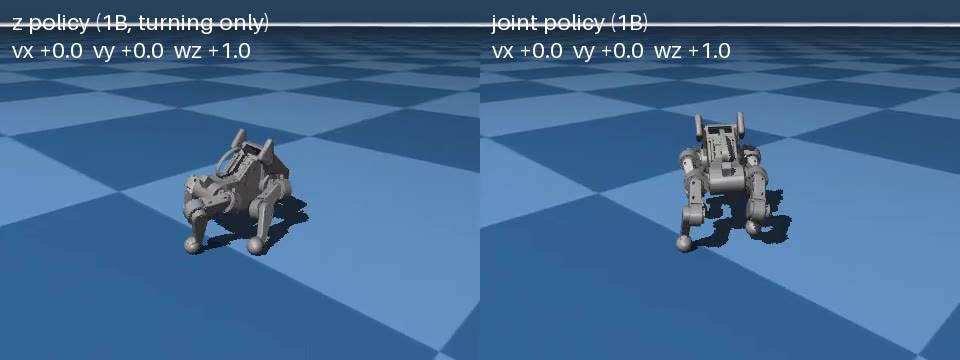
Three policies were trained separately for forward, sideways and turning commands, to be blended at run time. None of them learned to walk, with 334 M or with 1 B…
 영상
계단 난이도: 높이뿐 아니라 디딤면 길이
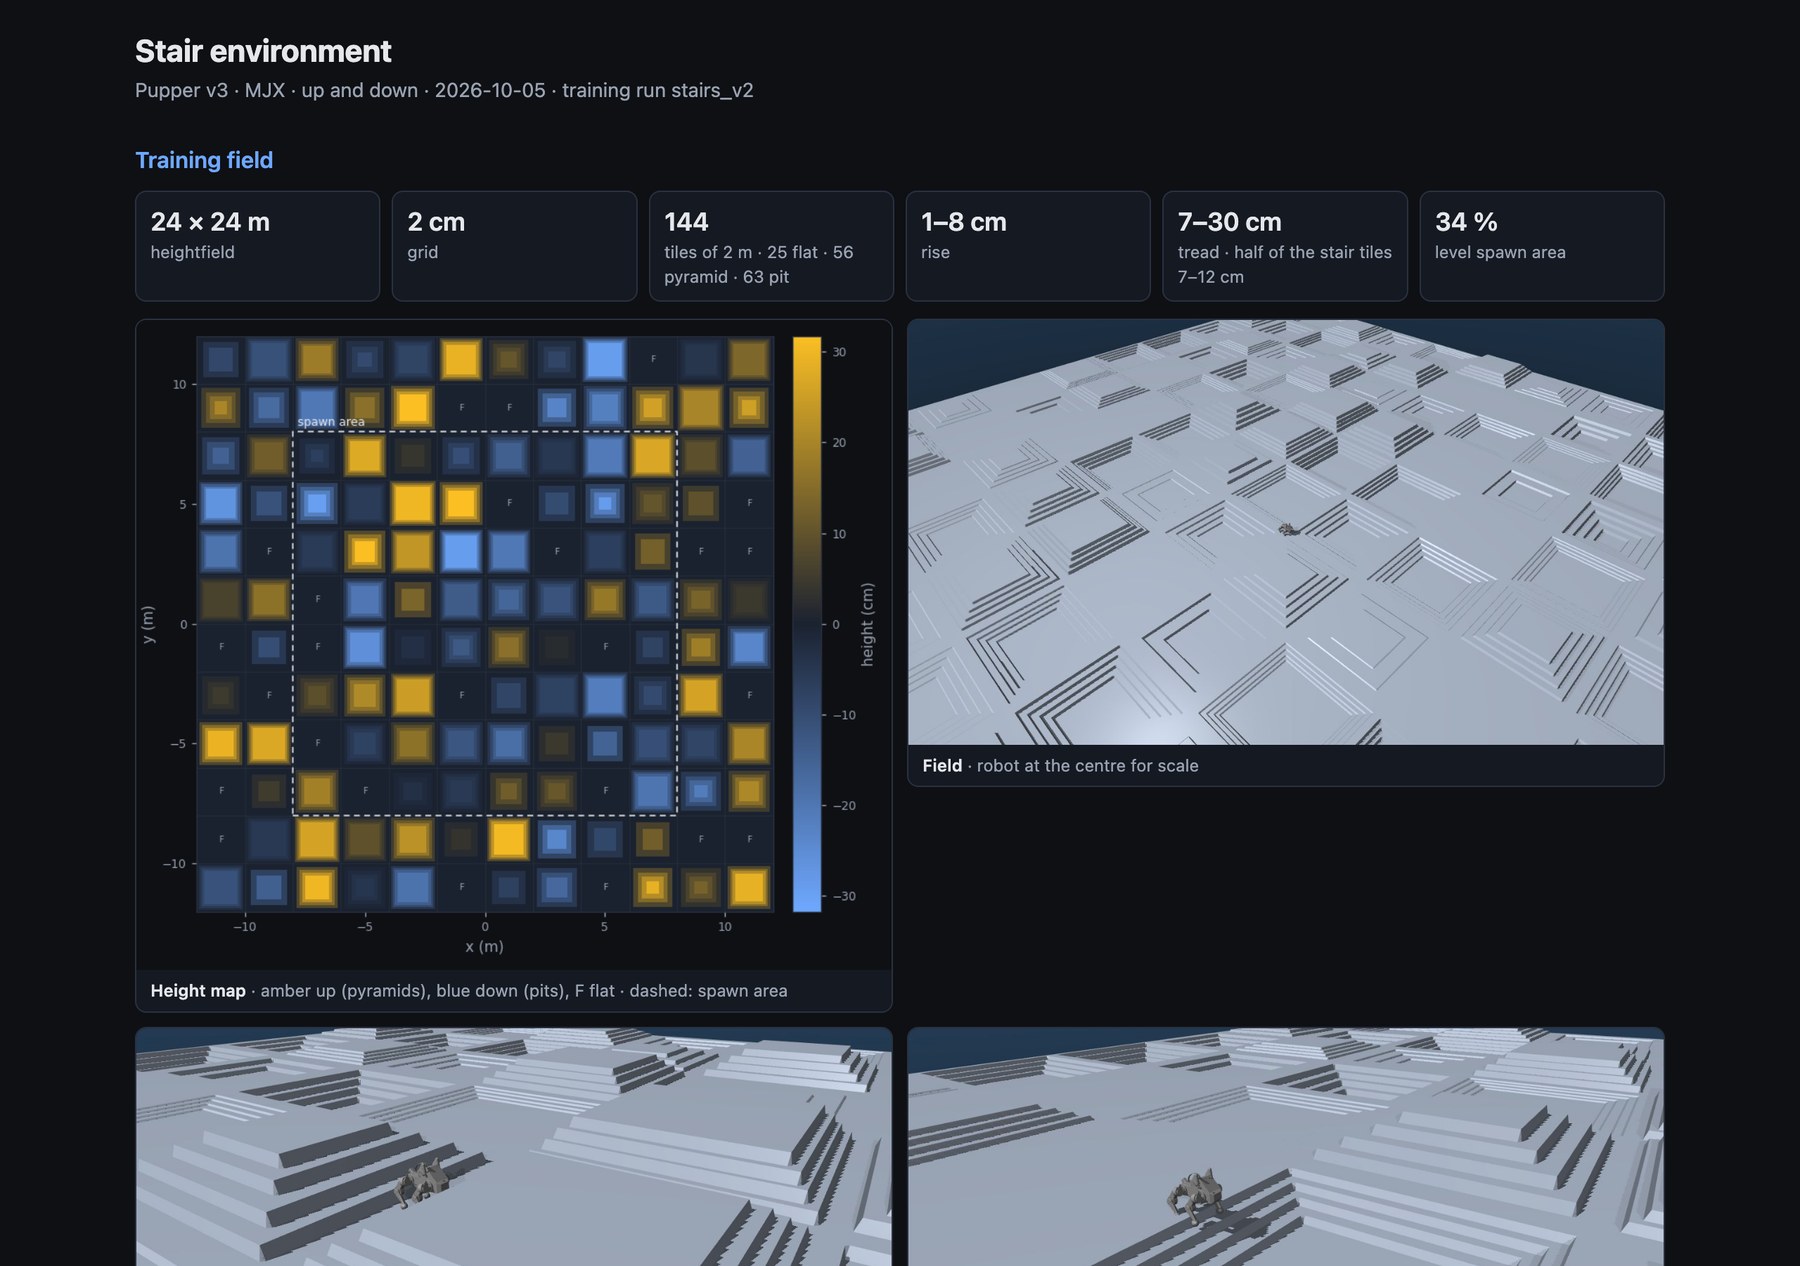
짧은 디딤면이 계단 통과를 크게 제한했습니다.
 리서치 노트
Driving the walking stack in simulation
The robot's ROS 2 stack runs with MuJoCo in place of the hardware and is driven from the browser with keys or a DualSense pad.
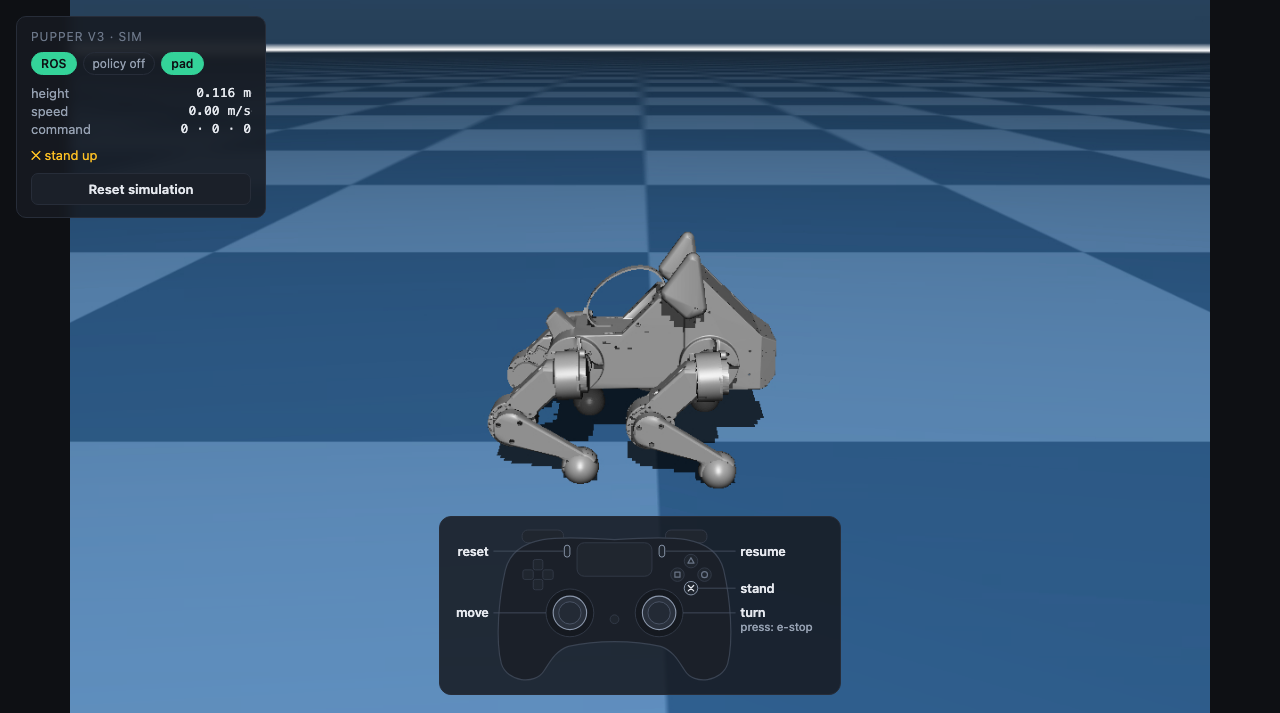 사진 / 그래프
Control software on the robot
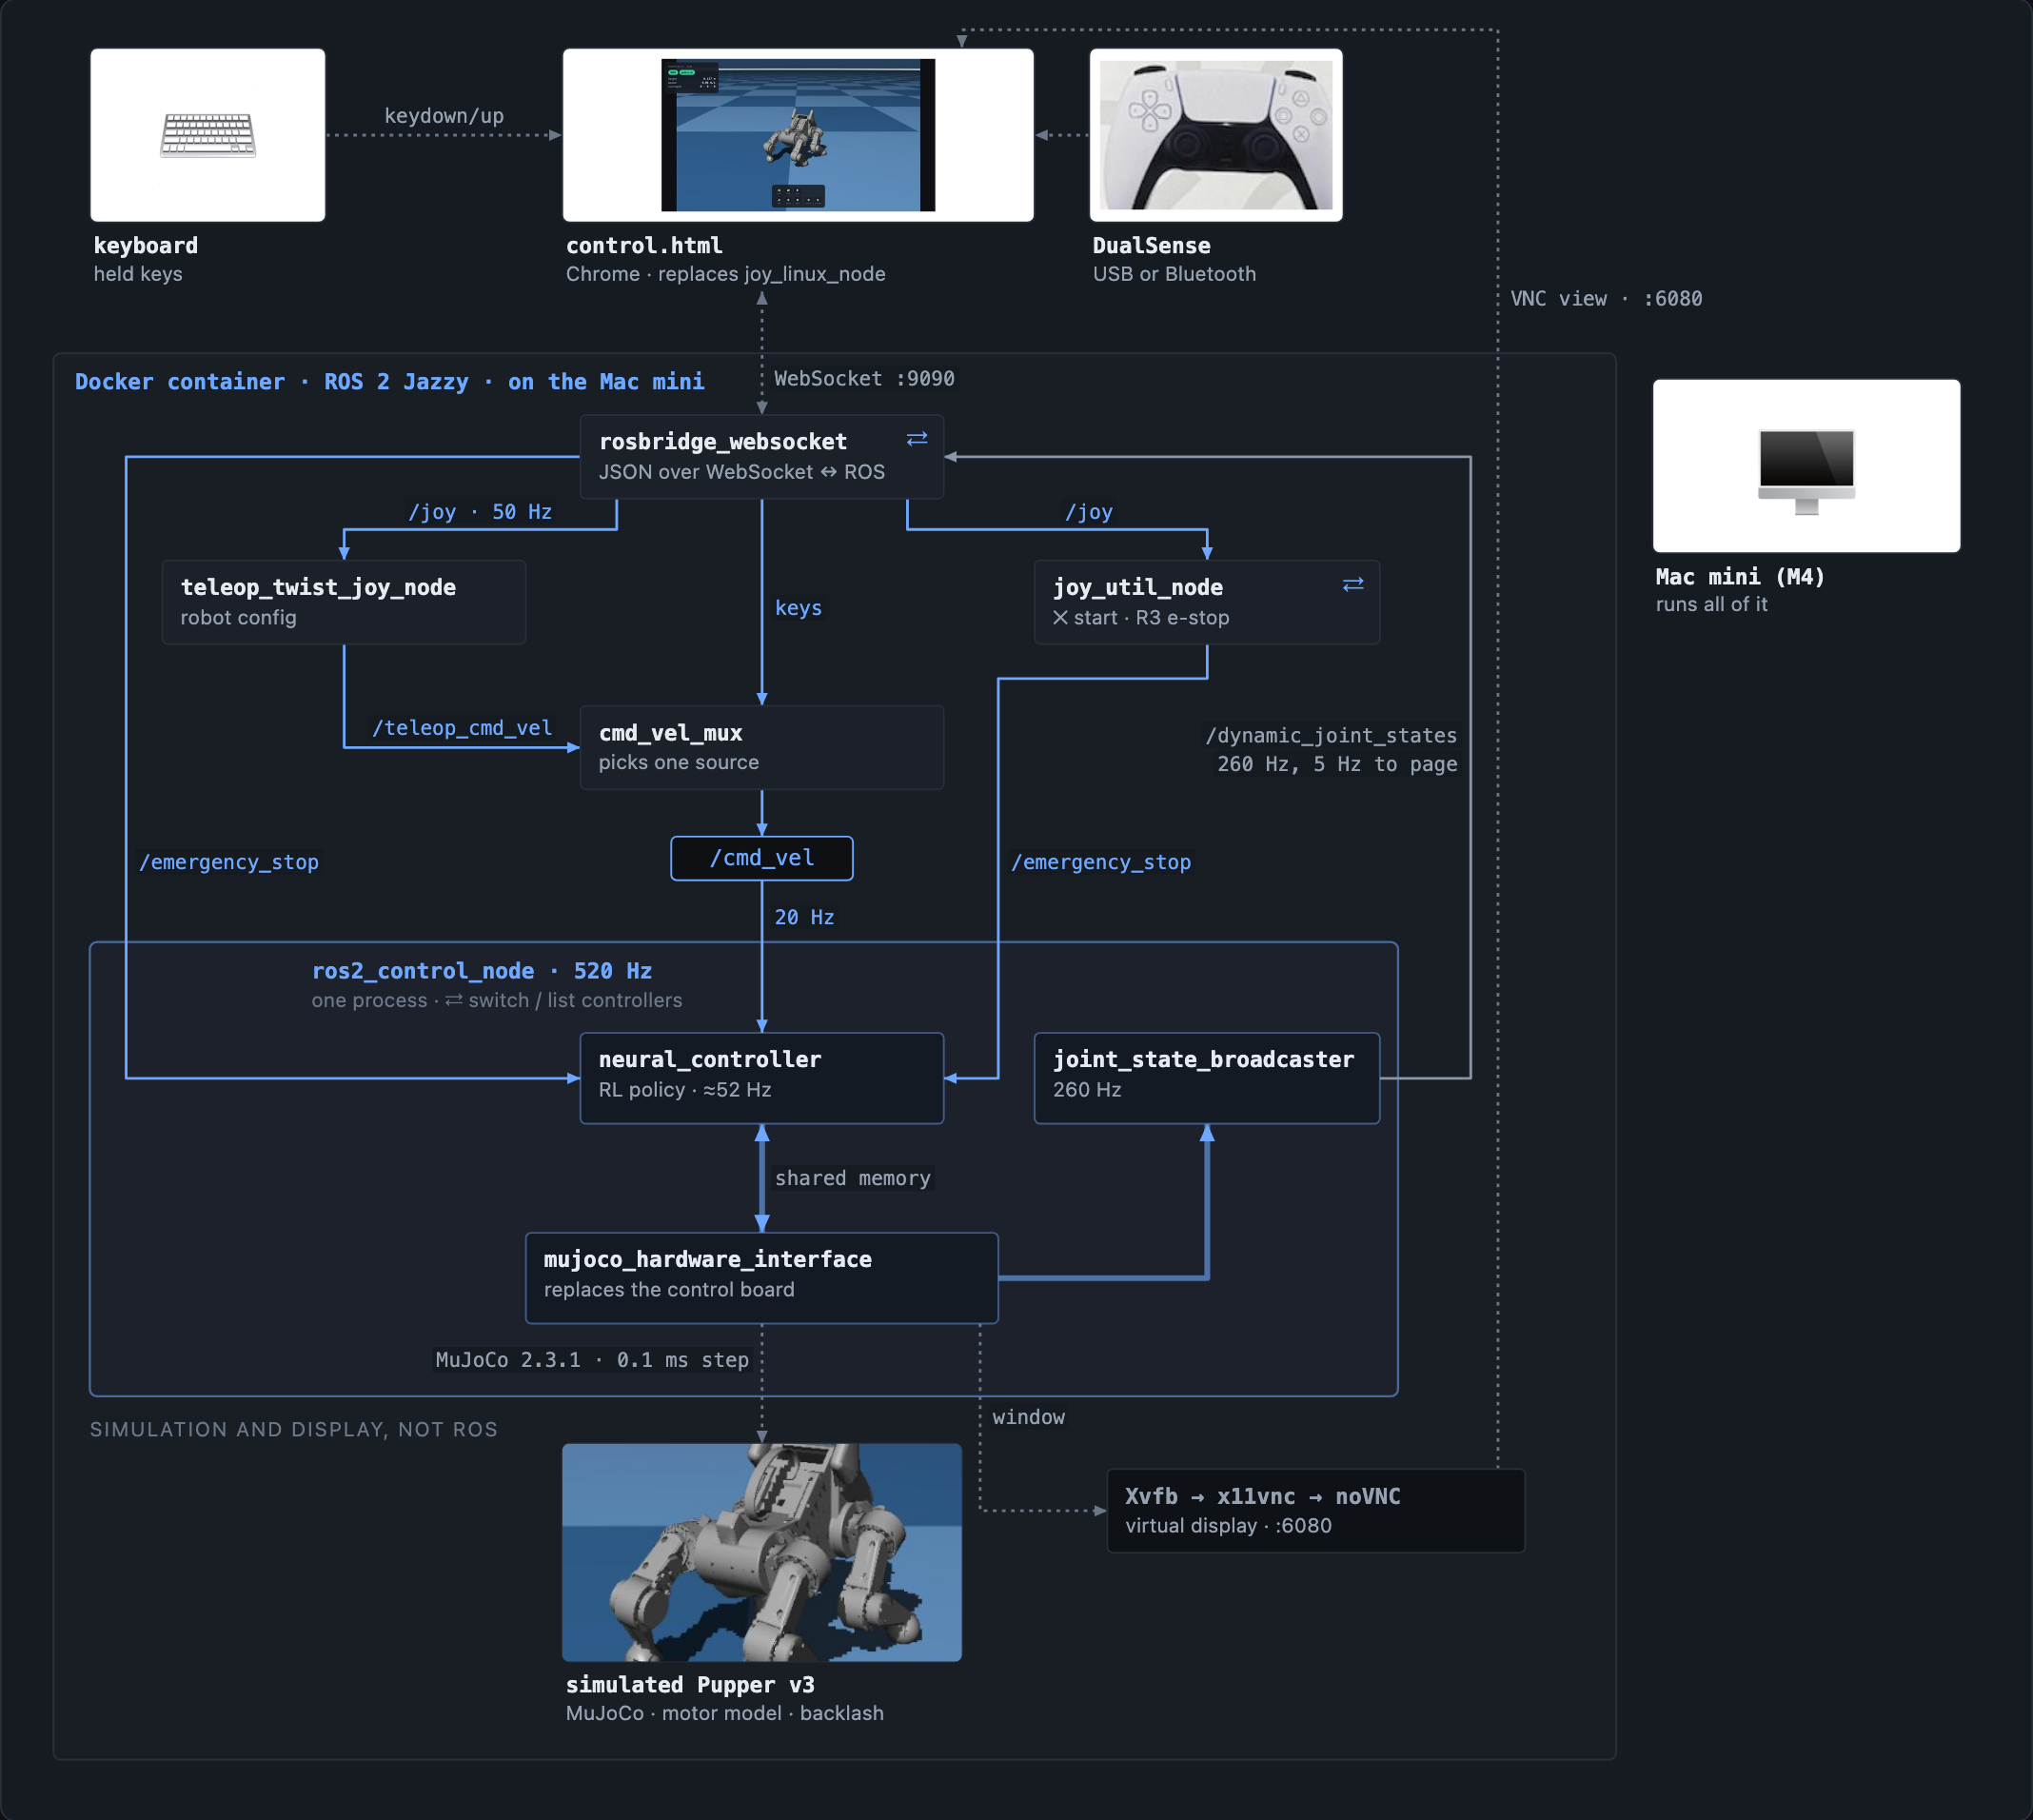
Gamepad, camera and voice commands reach the RL policy through ROS 2 on the Raspberry Pi 5, and the policy drives the 12 motors through the control board.
 시스템 다이어그램
Walking policy trained in simulation
The upstream Pupper v3 MJX pipeline, run on one lab GPU. One policy stands, walks, strafes and turns.
 영상